High-Performance Data Pipelines for Python
Datagrunt simplifies reading, writing, and converting CSV, Excel, Parquet, and PDF files. By uniting best-in-class engines—Polars for Rust-speed, DuckDB for local SQL, and PyArrow for columnar memory—Datagrunt abstracts away boilerplate, formatting limits, and delimiter headaches.
Write Clean, Intention-Revealing Code
from datagrunt import CSVReader, PDFReader

# 1. Zero-boilerplate CSV loading: auto-sniffs delimiter (comma, tab, semicolon)
# and processes with Polars (default) or DuckDB/PyArrow.
df = CSVReader("huge_data.csv").to_dataframe()

# 2. Unified PDF parsing: extracts structured tables, text, and images
# using PDFium or PyMuPDF, with optional Tesseract OCR.
document = PDFReader("invoice.pdf").to_dicts()
Core Components
Datagrunt wraps high-performance execution engines in a consistent, developer-first interface.
🧠 Intelligent Delimiter Inference
No more hardcoding `sep=','` or guessing delimiters. Datagrunt automatically sniffs and applies commas, semicolons, tabs, and pipes using advanced heuristics.
⚡ Multi-Engine Execution
Swap execution engines on the fly. Route queries to Polars for memory-efficient speed, DuckDB for local SQL analytics, or PyArrow for columnar serialization.
📄 Unified PDF & Table Parser
Extract text, tabular boundaries, and embedded images from PDFs in a single line. Utilizes PDFium and optional PyMuPDF with Tesseract OCR support.
🔄 Format Conversion Pipelines
Easily convert files between formats (CSV, Excel, Parquet, JSON, JSONL) with compression passthrough and worksheet sheet-by-sheet support.
Meet Datagrunt Studio
A free, open-source workbench for exploring, cleaning, and joining CSV and Excel files — powered by Datagrunt and DuckDB, running entirely on your machine.
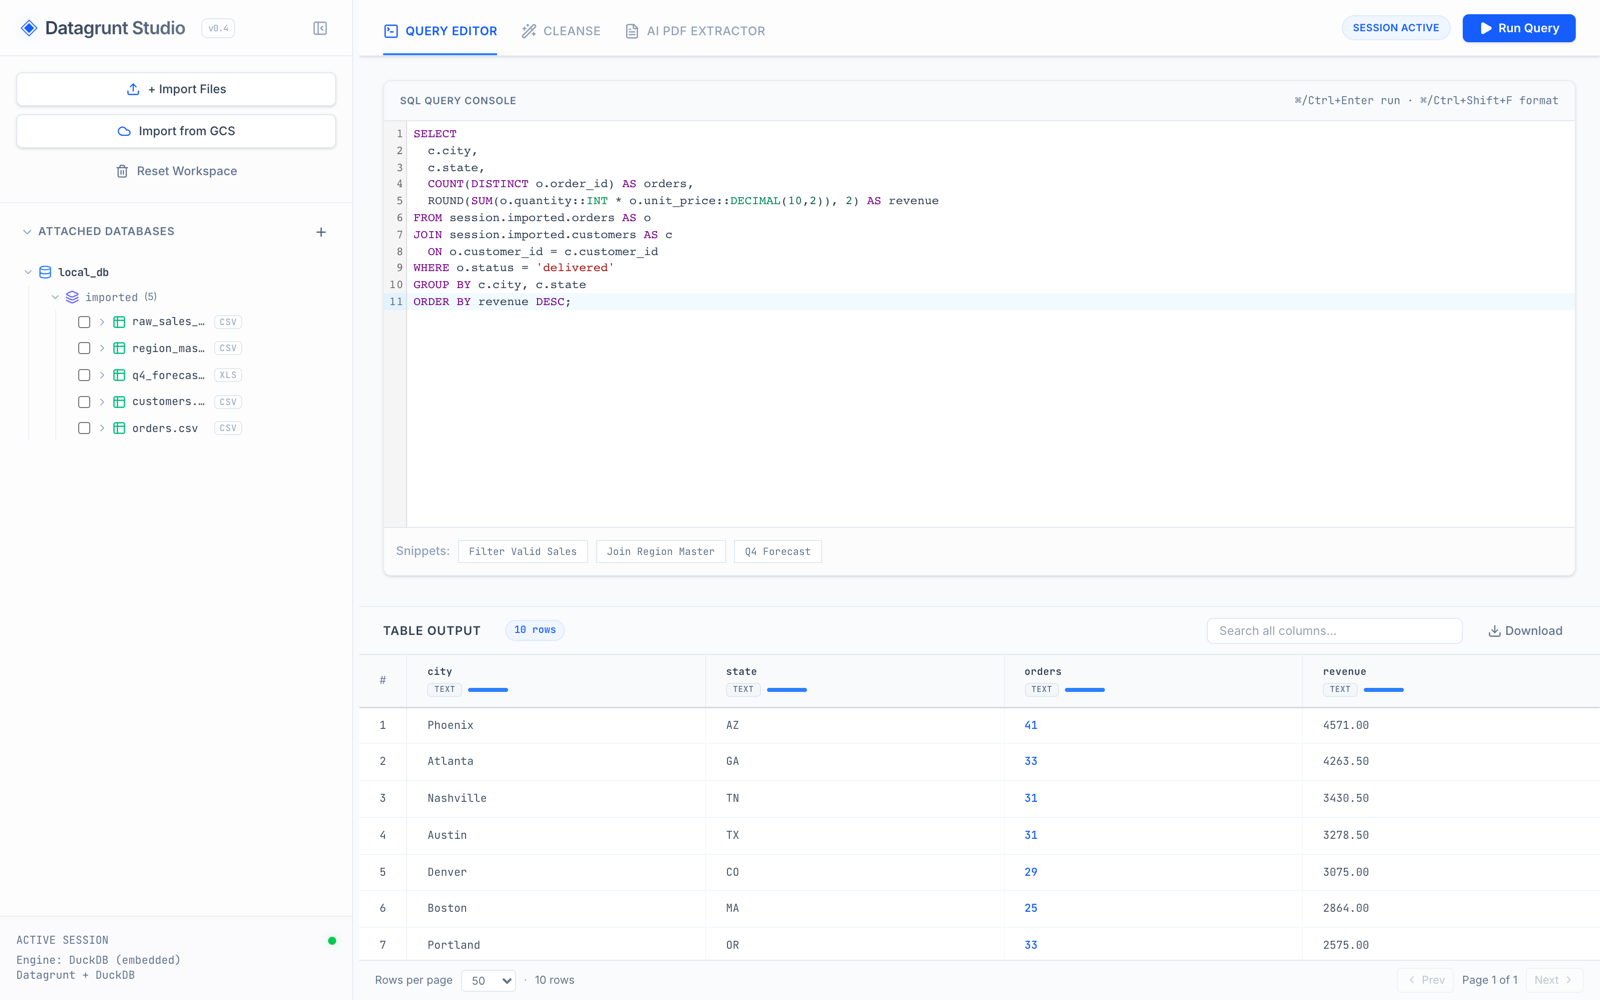
🔍 Query with SQL
Import CSV and Excel files — locally or from Google Cloud Storage — then explore and join them with DuckDB SQL in a full-featured editor.
🪄 Cleanse Visually
Build cleansing pipelines with a live preview: deduplicate rows, fill or drop nulls, rename columns, and cast types — then commit the result as a new table.
🤖 Extract from PDFs
Turn PDF tables into queryable data with AI extraction via Google Gemini — or keep everything on-device with a local Ollama model.
Supported Engines & Ecosystem
Datagrunt integrates industry-standard libraries to deliver maximum throughput.
Polars
Rust DataFrame Core
DuckDB
In-process Analytical SQL
PyArrow
Columnar Serialization